Jianping Jiang

Quantitative Researcher · Ubiquant

Jianping Jiang

I’m a quantitative researcher at Ubiquant. I joined in July 2026, following several years of research in computer vision and multimodal learning.

Previously, I worked on multimodal models at Ant Group and autonomous 3D characters with MMLab at NTU and SenseTime. This page brings together some of that work.

Jianping Jiang standing beside a tree

Selected work

All publications ↗

NeurIPS 2026Evaluations and Datasets Track · PosterProject lead
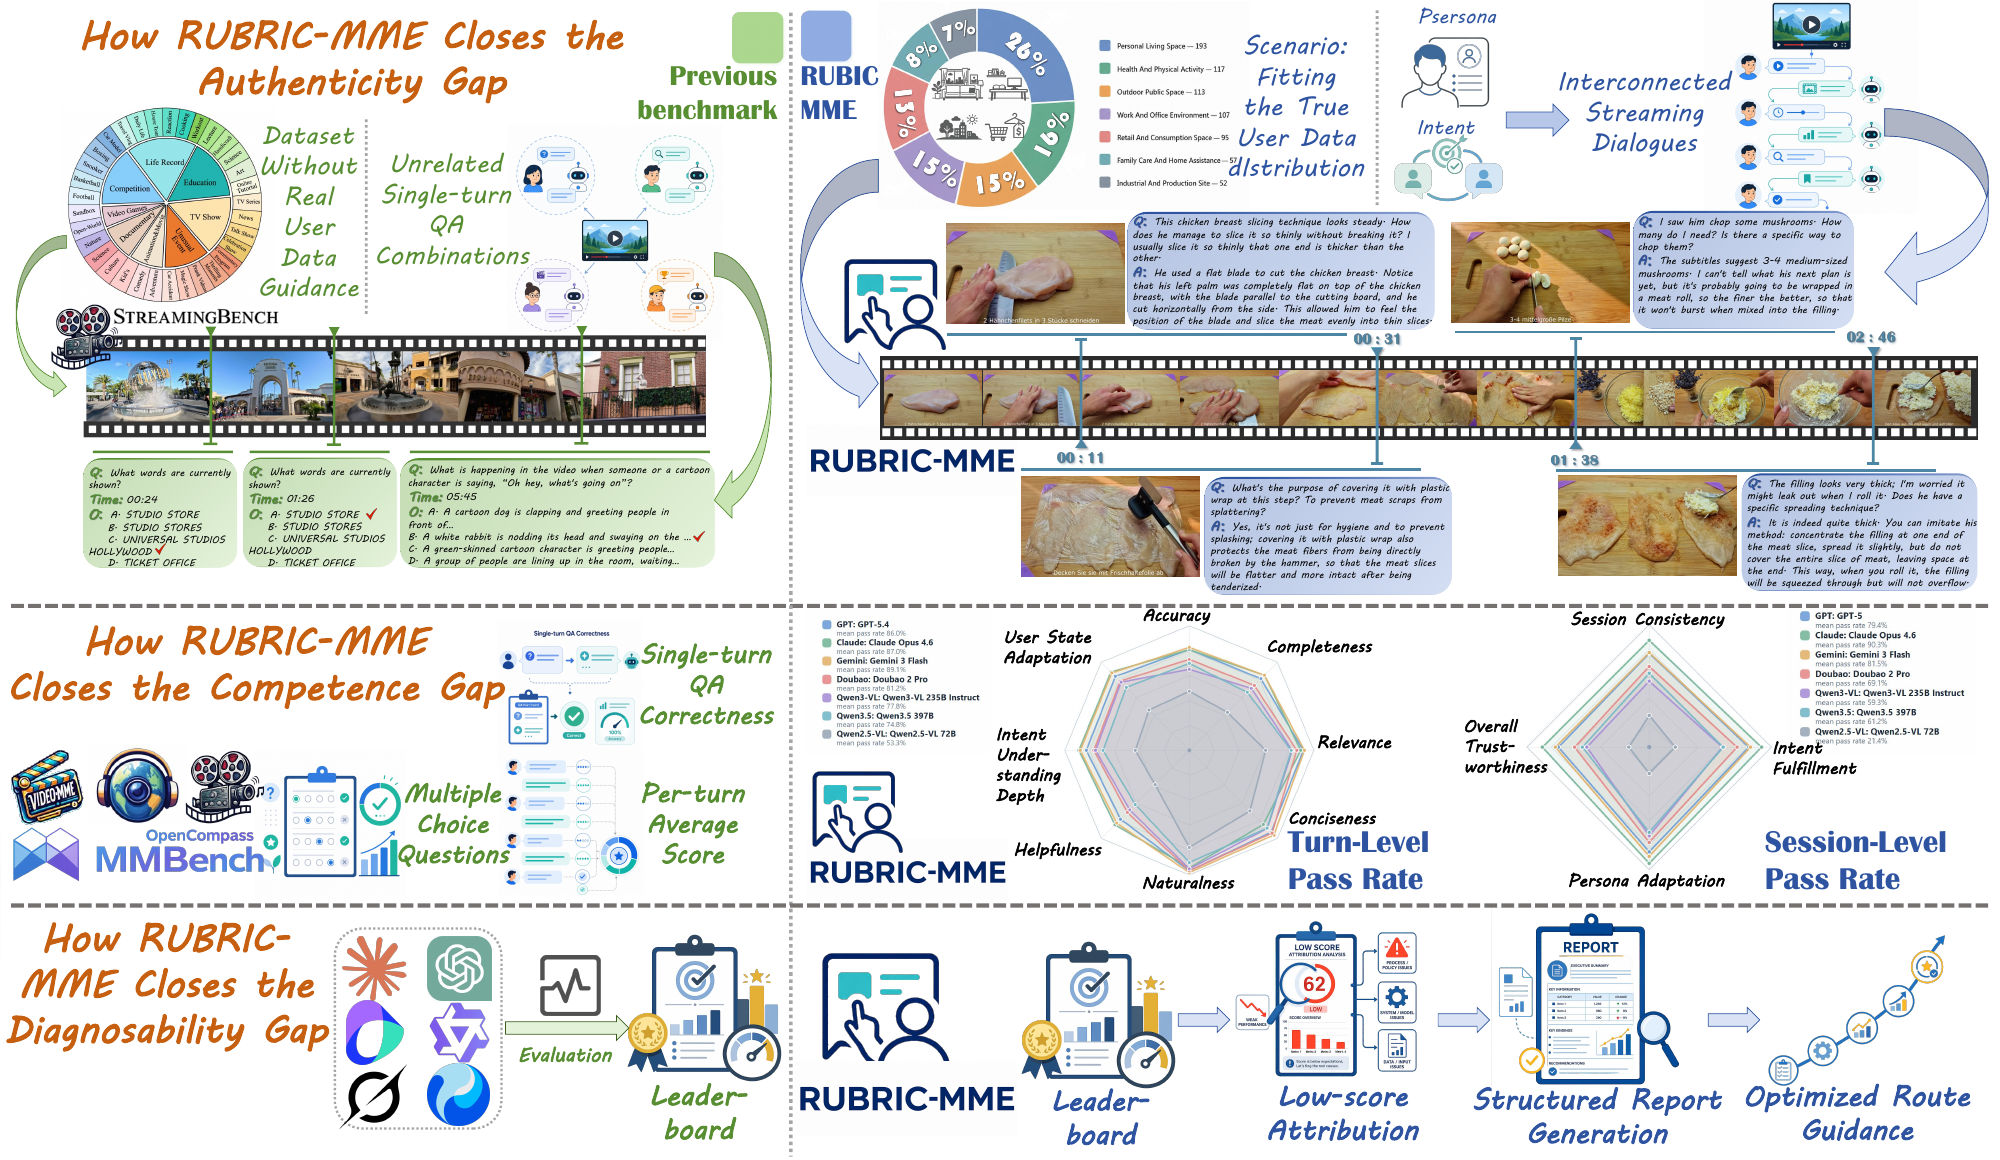
RUBRIC-MME overview: authentic user interactions, capability evaluation, and diagnostic analysis

RUBRIC-MME

Real-User Behavior-grounded Rubric for Multimodal Interaction Capability Evaluation

We study the gap between benchmark scores and real conversations, evaluating both individual responses and whole sessions, with analysis to help explain where models fall short.

Camera-ready in preparation; paper and materials will follow.
Jiajie Teng, Jianping Jiang, Huiyu Duan, Jingdong Chen, Yi Yuan, Guanming Yao, Sijing Wu, Yuqin Cao, Yixuan Gao, Xiongkuo Min, Guangtao Zhai.

Ant GroupTechnical report
Ming logo

Ming-flash-omni

Ming-flash-omni Preview · Ming-flash-omni 2.0

At Ant Group, I worked on video understanding and audiovisual interaction, including training data, post-training, and evaluation.

Ming Team.

CVPR 2025Co-first author
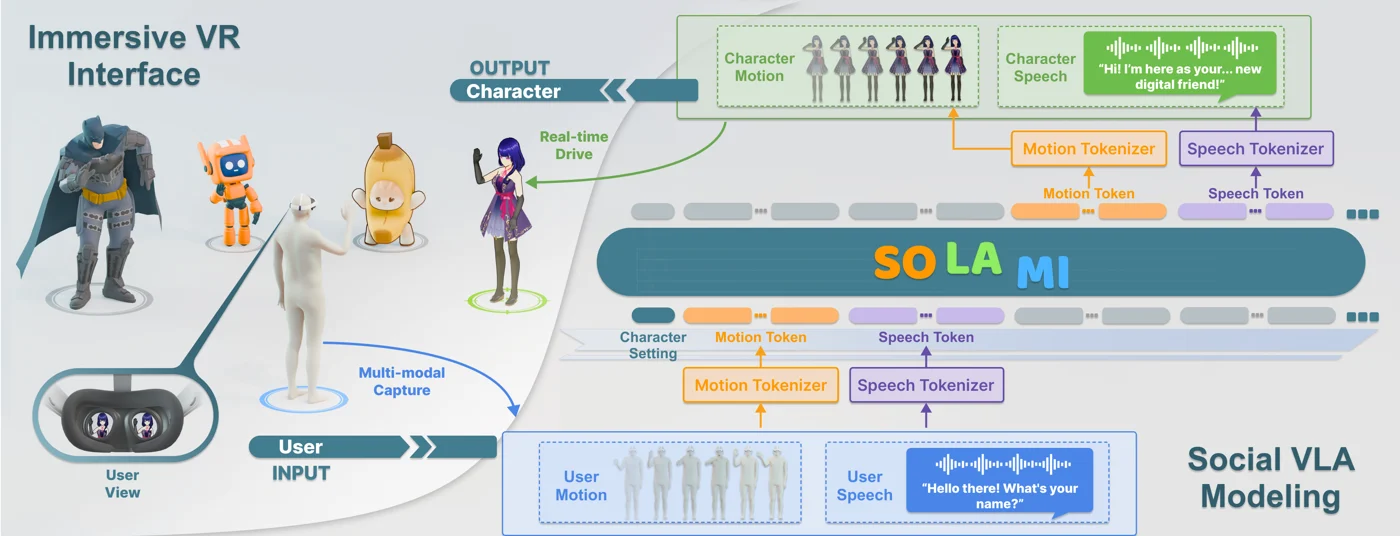
SOLAMI social vision-language-action model

SOLAMI

Social Vision-Language-Action Modeling for Immersive Interaction with 3D Autonomous Characters

A model that lets autonomous 3D characters respond to a person’s speech and movement with their own voice and body language.

CVPR 2024Co-first author
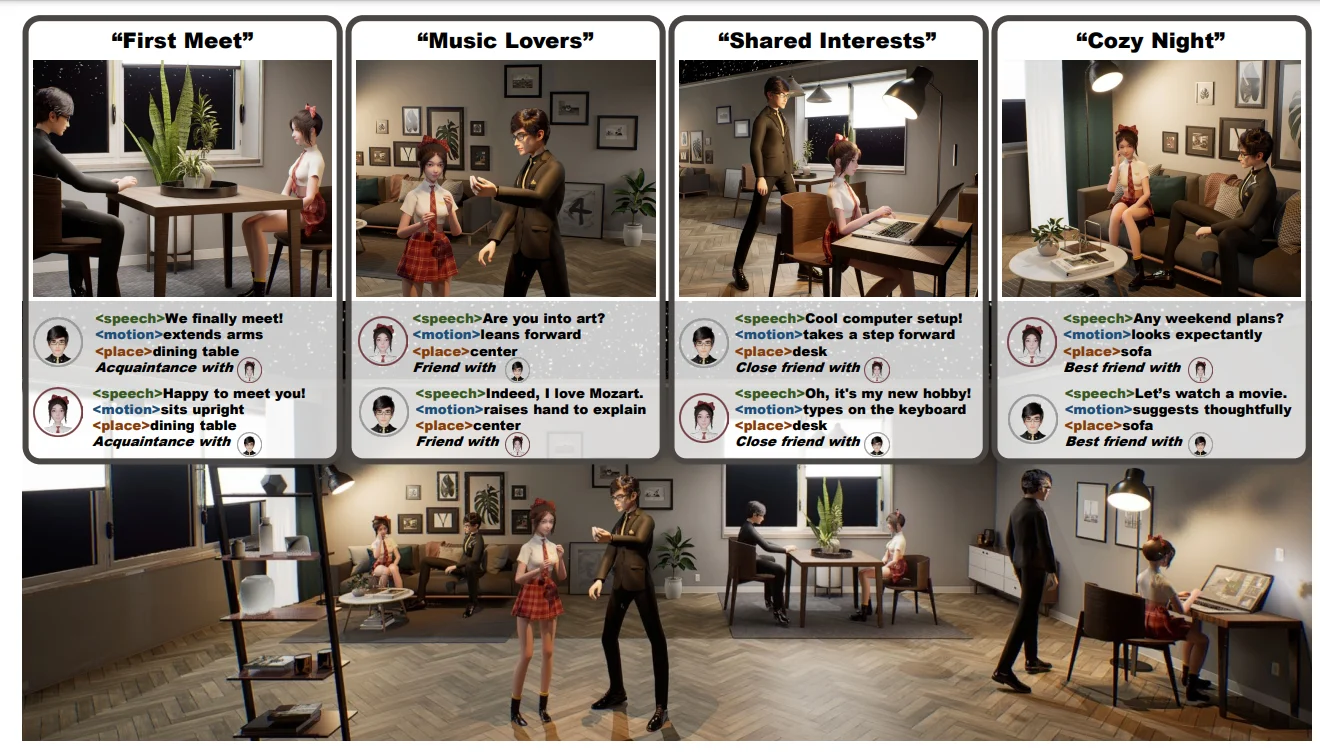
Digital Life Project research overview

Digital Life Project

Autonomous 3D Characters with Social Intelligence

A framework for 3D characters with memory, personality, and social behavior. My work connected ideas from psychology with language-model agents.

CVPR 2024Co-first author
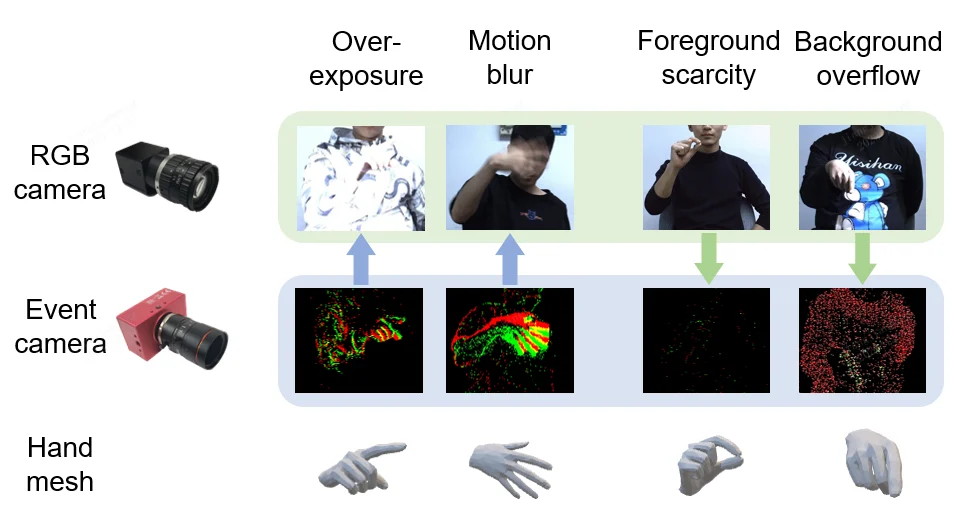
EvRGBHand event and RGB fusion research figure

EvRGBHand

Complementing Event Streams and RGB Frames for Hand Mesh Reconstruction

Combining event streams with RGB images to reconstruct hands under difficult lighting and fast motion.

TPAMI 2024Co-first author
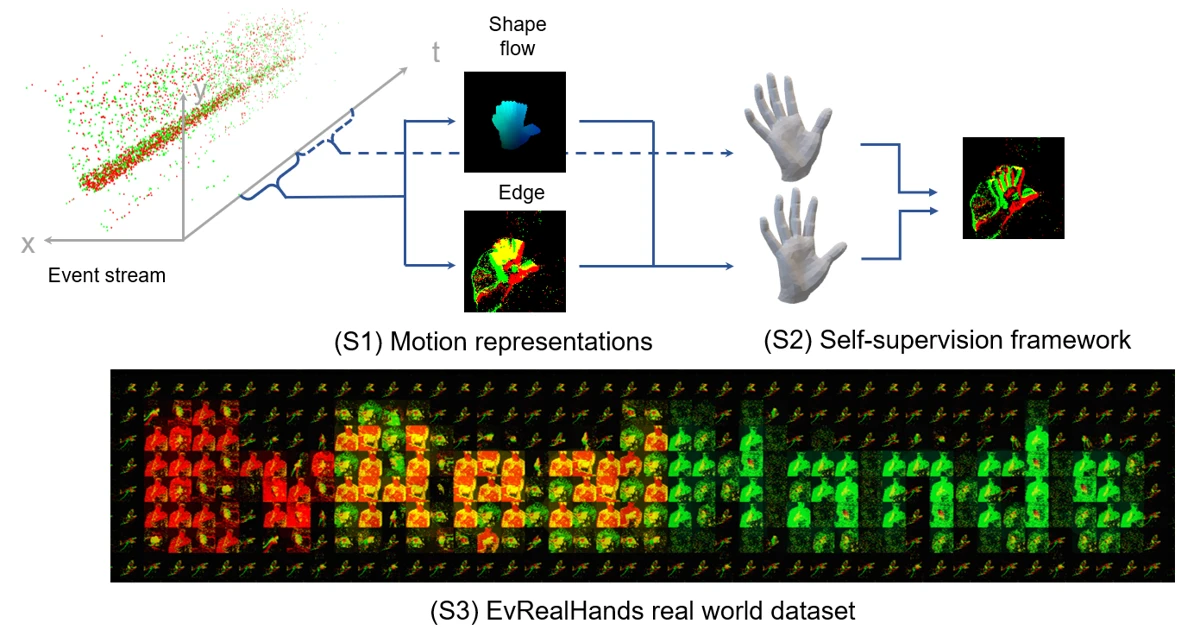
EvHandPose method and EvRealHands dataset

EvHandPose

Event-based 3D Hand Pose Estimation with Sparse Supervision

Estimating 3D hand poses from event-camera data with sparse annotations. This work also introduced the EvRealHands dataset.

Experience & education

2026.07 — present

Ubiquant

Quantitative Researcher
2025.06 — 2026.06

Ant Group

Multimodal Model Researcher

Video understanding, audiovisual interaction, data synthesis, and automated evaluation.

Working at Ant Group was a truly terrible experience for me.

2023.08 — 2025.04

MMLab @ NTU & SenseTime Research

Researcher · Collaborating with Prof. Ziwei Liu

Autonomous 3D characters, social intelligence, and multimodal interaction.

2020.09 — 2023.07

Peking University

M.S. in Computer Science & Technology

Camera Intelligence Lab · Event-based perception and hand interaction. Research collaboration with Prof. Boxin Shi.

2016.08 — 2020.07

Tsinghua University

B.Eng. in Electronic Engineering · Minor in Psychology

Other experiences

2023 · BAAIResearch intern · Working with Yue Cao and Xinlong Wang.

2021 · ByteDanceAI product management intern · Intelligent video creation and AR research.

2019–2021 · AREYECore founding-team member · AR experiences for museums and cultural spaces.

Writing

Essays in Chinese
2023

毕业感想

Reflections on research, personal growth, and life at the end of graduate school.

2021

AR 眼镜之痛

An early look at the limits of AR hardware, from optics and displays to interaction.

WeChat public account

五道口折叠

You can also find my writing on WeChat. Scan the code to follow.

QR code for the WeChat public account 五道口折叠

Along the way

LLMs × Trading ↗

A reading list on language models in financial research and trading, collected as I explored the field.

Contact

For research discussions or to get in touch, you can reach me by email.